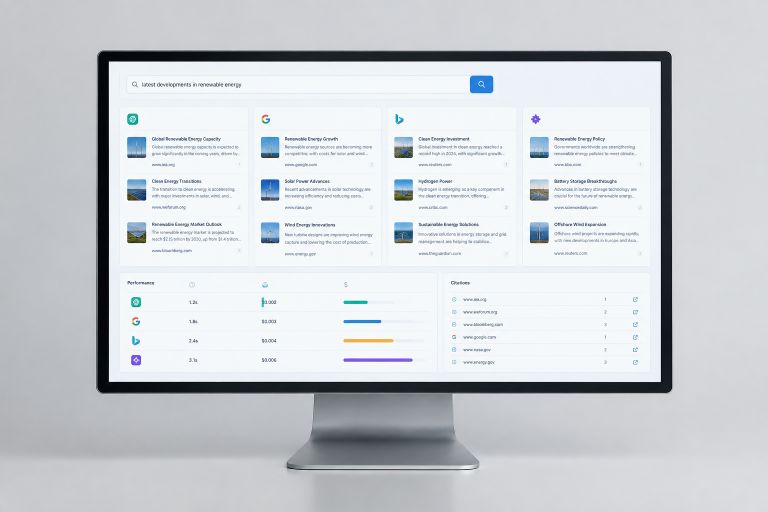
A Practical Guide to Comparing Web Search APIs for AI Agents
Table Of Contents
- Why The Choice Matters
- Define The Agent’s Workload
- Check Search Quality And Freshness
- Review Content And Response Format
- Measure Latency In Real Conditions
- Calculate The Real Cost
- Test Sources And Citations
- Run A Fair Provider Bake-Off
- Review Privacy And Security
- Make The Final Decision
Choosing a web search API is not simply a matter of comparing result counts or published request prices. An AI agent can only produce a dependable answer when it retrieves relevant, up-to-date information and connects its claims to usable evidence. Teams evaluating providers can begin by reviewing how Exa compares with Brave Search, then test each option against the specific work their own agent must perform.
A research agent, for example, may need to find a newly published policy, verify its effective date, read the original document, and cite the exact passage that supports its conclusion. A search API that returns a fast list of loosely related links may not be enough. Retrieval quality, freshness, content access, and source handling must work together.
Why The Choice Matters
Search is often the first dependency in an agent workflow. If the retrieved material is incomplete, stale, ambiguous, or unsupported, the model may need additional searches, extraction calls, or clarification steps. That adds delay and cost while still leaving room for an incorrect answer. The fastest endpoint is therefore not automatically the best endpoint.
Evaluate the complete path from a user question to a final, supported response. This includes search, page retrieval, ranking, model context, citations, retries, and failure handling. That approach turns a feature comparison into an engineering decision.
Define The Agent’s Workload
Describe the job before comparing providers. “Web search” can mean monitoring recent news, locating documentation, finding companies, researching people, tracking site changes, or answering multi-step questions. Each workload places different demands on the retrieval system.
Questions To Ask First
- Does the agent need information published or updated recently?
- Will it search for people, companies, products, technical documents, or general web pages?
- Does it need short passages, full-page content, or structured fields?
- Will the agent perform one lookup or a sequence of searches?
- Must every final answer include verifiable citations?
- Does the application require predictable JSON fields and clear error responses?
Write these requirements down as acceptance criteria. Doing so prevents a team from favoring a provider based on an impressive demo that does not reflect the production workflow.
Check Search Quality And Freshness
Search quality is not just whether a result appears related to the query. The more important question is whether the returned material lets the agent answer correctly. A relevant-looking page may omit the date, bury the needed fact, or discuss a similarly named organization.
Useful Quality Checks
- Relevant sources appear near the top of the result set.
- Results match the meaning of the request rather than only repeated keywords.
- Rare names, abbreviations, and similar company names are resolved accurately.
- Recent materials appear when the task depends on current information.
- Returned passages contain enough context to support a grounded answer.
Create a test set from real user requests. Include straightforward searches, obscure entities, current questions, technical research, and multi-step tasks. Generic test queries rarely reveal the failures that affect actual users.
Review Content And Response Format
Some APIs return titles, URLs, and snippets. Others also provide extracted page text, clean Markdown, highlights, dates, or structured metadata. The difference matters because an agent that receives only links may need another service to fetch and parse each page.
Response Fields To Compare
- Page title and canonical source URL
- Publication date or update date when available
- Relevant snippets or highlighted passages
- Full-page text or clean Markdown
- Structured metadata and entity fields
- Relevance indicators, if provided
- Consistent empty results, timeout, and error responses
Compact passages can reduce the amount of text sent to the model. Full-page content can be more appropriate when surrounding definitions, exceptions, or technical details determine whether an answer is accurate.
Measure Latency In Real Conditions
One successful request does not establish production speed. Agents may search multiple times, retrieve multiple pages, retry an unavailable endpoint, and then ask a model to synthesize the evidence. Measure the full workflow under realistic concurrency and query patterns.
Latency Measurements To Record
- Median response time, often called p50
- Slower responses, including p95 and p99
- Time for content extraction or page processing
- Timeout frequency and retry behavior
- Rate-limit responses
- Total time from user question to final answer
Small per-request differences can compound in sequential research loops. A delay that seems minor in a single search becomes more noticeable when an agent must perform many dependent searches before responding.
Calculate The Real Cost
Published search pricing is only one part of the cost. A lower-cost search request may create additional expenses if it requires page extraction, repeated retrieval, larger model context, or more retries to reach a useful answer.
Cost Categories To Include
- Search and content extraction requests
- Input tokens sent to the model
- Output tokens in the final response
- Retries, fallbacks, and failed calls
- Logging, observability, storage, and evaluation infrastructure
Track cost per resolved task rather than cost per request alone. A resolved task should meet the standard your product requires, such as a correct answer with adequate evidence, acceptable response time, and no unsupported claims.
Test Sources And Citations
Citation quality has two separate requirements. First, the cited source must be relevant and sufficiently authoritative for the claim. Second, the answer must accurately represent what that source says. A precise-looking link is not useful if the linked page does not support the statement beside it.
- Check whether the cited page contains the claimed fact.
- Confirm that the source is recent enough for the question.
- Identify duplicated pages or sources that merely repeat one another.
- Review whether the source is appropriate for the subject.
- Test how the workflow presents conflicting evidence.
Manually review a sample of agent answers before deployment. Save citation failures as test cases, especially when the answer was fluent, but the evidence was weak, missing, or misapplied.
Run A Fair Provider Bake-Off
A useful provider evaluation is repeatable. Collect 30 to 100 representative questions, group them by use case, and keep the model, prompts, query limits, and output format consistent across providers.
- Run every provider against the same test set.
- Repeat tests to account for changing web results.
- Score answer accuracy, source support, latency, cost, and failure rate.
- Review individual disagreements, not just averages.
- Turn difficult failures into permanent regression tests.
Review Privacy And Security
Search queries can expose customer names, internal project details, or sensitive business questions. Review retention, access controls, regional processing needs, and whether queries may be used beyond delivering the service. Security planning should also account for prompt injection or malicious instructions embedded in retrieved pages.
Use synthetic data during early testing where possible. Before sending production queries, document approved data types, restrict secrets from prompts, and define how the application will treat untrusted web content.
Make The Final Decision
The best web search API depends on the agent’s job. For current information tasks, prioritize freshness controls and useful data metadata. For research and retrieval-augmented generation, prioritize relevant passages, accessible content, and reliable source support. For high-volume loops, focus on stable latency, rate limits, and predictable costs. For privacy-sensitive workflows, place data handling and retention controls near the top of the decision criteria.
Select a provider only after testing realistic questions through the complete workflow. A careful evaluation provides AI agents with a stronger foundation for timely, well-supported, and cost-conscious answers.